Teams love to ship a demo that "does RAG." Vector database, a few PDFs, a chat box. Applause in the standup. Screenshot in the investor update.
Production is less romantic. Chunking strategies fail on tables and policies. Embeddings drift as documents change. Hallucinations sneak past soft prompts. Latency budgets collapse under real concurrent traffic. Suddenly the demo that answered three questions perfectly cannot survive a Tuesday afternoon.
Contracts, not magic
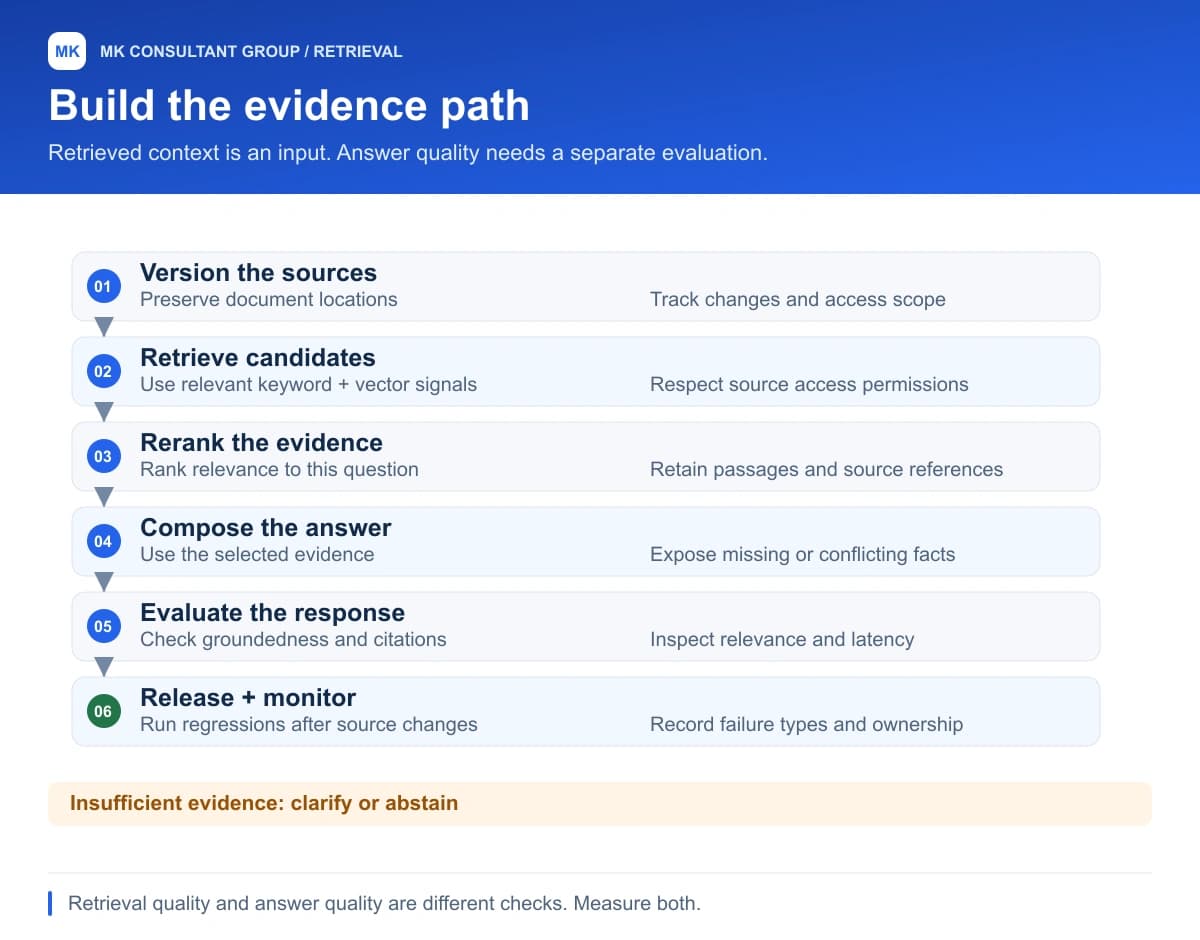
Treat RAG as a subsystem with contracts: hybrid retrieval (keyword + dense), rerankers that actually improve precision, evaluation harnesses that catch regressions before users do, and hard guardrails that refuse to invent citations.
Without those, you don't have a product. You have a prototype with a marketing site. The gap between "it found something" and "it found the right clause under compliance review" is where most AI budgets quietly evaporate.
MK Labs prototypes those subsystems internally before they ever touch a client environment. That's how we avoid shipping theater.
What we measure
We care about grounded answer rate, citation fidelity, p95 latency, and failure taxonomy, not just "felt helpful in a meeting." If you cannot say how retrieval quality moved week over week, you are flying blind with a very expensive compass.
RAG is infrastructure. Treat it like infrastructure: versioned, tested, owned. The chatbot is the skin. The subsystem is the product.